swap-stack: duo config — qwen3-4b full GPU, ornith-35b pure CPU
Duo group (resident main+subagent for pi): flip VRAM to the small model.
Ornith experts never touch VRAM; its dense-on-GPU split starved qwen to
176 MiB / 5.8 t/s concurrent. After flip: qwen 43 t/s, ornith 8 t/s.
CUDA_VISIBLE_DEVICES= required for ornith — ngl 0 still allocates ~1GB
pp compute buffer on CUDA builds (OOM+segfault). Duo section in
MOE-FINDINGS.md; also snapshots prior swap-stack migration state.

Co-Authored-By: Claude Fable 5 <noreply@anthropic.com>
This commit is contained in:

 Claude Fable 5
@@ -0,0 +1,19 @@
|
||||
# Tri-binary swap-stack: llama-swap + three llama-server builds.
|
||||
# /app/llama-server TurboQuant fork (May 2026) — turbo2/3/4 KV, needed by 9B configs
|
||||
# /app-upstream/llama-server upstream master (Jul 2026) — newest MoE/arch work
|
||||
# /app/llama-server-ik ik_llama.cpp — -ser / -fmoe / -rtr, fast IQ-quant CPU kernels
|
||||
# config.yaml picks the binary per model (env: LD_LIBRARY_PATH for upstream).
|
||||
FROM local/llama-cpp-upstream:server-cuda-sm75-mmq AS upstream
|
||||
FROM local/ik-llama:server-cuda-sm75 AS ik
|
||||
|
||||
FROM local/llama-cpp-turboquant:server-cuda-sm75-mmq
|
||||
|
||||
COPY --from=upstream /app /app-upstream
|
||||
COPY --from=ik /llama-server /app-ik/llama-server
|
||||
COPY --from=ik /usr/local/lib/libllama.so /usr/local/lib/libggml.so /usr/local/lib/libmtmd.so /app-ik/
|
||||
COPY --from=ik /usr/local/cuda-12.4/targets/x86_64-linux/lib/libcudart.so.12 /usr/local/cuda-12.4/targets/x86_64-linux/lib/libcublas.so.12 /usr/local/cuda-12.4/targets/x86_64-linux/lib/libcublasLt.so.12 /app-ik/
|
||||
COPY llama-swap /app/llama-swap
|
||||
|
||||
# config.yaml is bind-mounted at runtime (see compose.yaml) so edits
|
||||
# only need a container restart, not a rebuild.
|
||||
ENTRYPOINT ["/app/llama-swap", "-config", "/app/config.yaml", "-listen", ":8080"]
|
||||
@@ -0,0 +1,9 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2024 Benson Wong
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy of this software and associated documentation files (the “Software”), to deal in the Software without restriction, including without limitation the rights to use, copy, modify, merge, publish, distribute, sublicense, and/or sell copies of the Software, and to permit persons to whom the Software is furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED “AS IS”, WITHOUT WARRANTY OF ANY KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
|
||||
@@ -0,0 +1,296 @@
|
||||

|
||||
|
||||

|
||||

|
||||
|
||||
# llama-swap
|
||||
|
||||
Run multiple generative AI models on your machine and hot-swap between them on demand. llama-swap works with any OpenAI and Anthropic API compatible server and is used by thousands of people to power their local AI workflows.
|
||||
|
||||
Built in Go for performance and simplicity, llama-swap has zero dependencies and is incredibly easy to set up. Get started in minutes - just one binary and one configuration file.
|
||||
|
||||
## Features:
|
||||
|
||||
- ✅ Easy to deploy and configure: one binary, one configuration file. no external dependencies
|
||||
- ✅ On-demand model switching
|
||||
- ✅ Use any local OpenAI compatible server (llama.cpp, vllm, tabbyAPI, stable-diffusion.cpp, etc.)
|
||||
- future proof, upgrade your inference servers at any time.
|
||||
- ✅ OpenAI API supported endpoints:
|
||||
- `v1/completions`
|
||||
- `v1/chat/completions`
|
||||
- `v1/responses`
|
||||
- `v1/embeddings`
|
||||
- `v1/models` - list available models
|
||||
- `v1/audio/speech` ([#36](https://github.com/mostlygeek/llama-swap/issues/36))
|
||||
- `v1/audio/transcriptions` ([docs](https://github.com/mostlygeek/llama-swap/issues/41#issuecomment-2722637867))
|
||||
- `v1/audio/voices`
|
||||
- `v1/images/generations`
|
||||
- `v1/images/edits`
|
||||
- ✅ Anthropic API supported endpoints:
|
||||
- `v1/messages`
|
||||
- `v1/messages/count_tokens`
|
||||
- ✅ llama-server (llama.cpp) supported endpoints
|
||||
- `v1/rerank`, `v1/reranking`, `/rerank`
|
||||
- `/infill` - for code infilling
|
||||
- `/completion` - for completion endpoint
|
||||
- `/props` - requires `?model={model_id}` query parameter to be provided. The autoload parameter is not supported and will be ignored.
|
||||
- ✅ SDAPI via [stable-diffusion.cpp's server](https://github.com/leejet/stable-diffusion.cpp/tree/master/examples/server)
|
||||
- `/sdapi/v1/txt2img`
|
||||
- `/sdapi/v1/img2img`
|
||||
- `/sdapi/v1/loras` - requires `model` in request body to fetch the correct loras
|
||||
- ✅ llama-swap API
|
||||
- `/ui` - web UI
|
||||
- `/upstream/:model_id` - direct access to upstream server ([demo](https://github.com/mostlygeek/llama-swap/pull/31))
|
||||
- `/running` - list currently running models ([#61](https://github.com/mostlygeek/llama-swap/issues/61))
|
||||
- `POST /api/models/unload` - manually unload all running models ([#58](https://github.com/mostlygeek/llama-swap/issues/58))
|
||||
- `POST /api/models/unload/:model_id` - unload a specific model
|
||||
- `/logs` - remote log monitoring
|
||||
- `GET /logs` returns buffered plain text logs.
|
||||
- If `Accept: text/html` is sent, `/logs` redirects to `/ui/`.
|
||||
- `GET /logs/stream` keeps the connection open for live log streaming.
|
||||
- Stream endpoints send buffered history first by default; add `?no-history` to stream only new lines.
|
||||
- `GET /logs/stream/proxy` streams proxy logs only.
|
||||
- `GET /logs/stream/upstream` streams upstream process logs only.
|
||||
- `GET /logs/stream/{model_id}` streams logs for one model (including IDs with slashes, like `author/model`).
|
||||
- `/health` - just returns "OK"
|
||||
- `/metrics` - system and GPU metrics for prometheus
|
||||
- ✅ API Key support - define keys to restrict access to API endpoints
|
||||
- ✅ Customizable
|
||||
- Run concurrent models with a custom DSL swap matrix ([#643](https://github.com/mostlygeek/llama-swap/issues/643))
|
||||
- Automatic unloading of models after timeout by setting a `ttl`
|
||||
- Docker and Podman support using `cmd` and `cmdStop` together
|
||||
- Preload models on startup with `hooks` ([#235](https://github.com/mostlygeek/llama-swap/pull/235))
|
||||
- Apply filters to requests to control inference with `stripParams`, `setParams` and `setParamsByID`
|
||||
|
||||
### Web UI
|
||||
|
||||
llama-swap includes a real time web interface with a playground for testing out all sorts of local models:
|
||||
|
||||
<img width="1094" height="667" alt="image" src="https://github.com/user-attachments/assets/a79b3cea-5ee1-45f1-8db9-5f5331690e64" />
|
||||
|
||||
View detailed token metrics:
|
||||
|
||||
<img width="1090" height="672" alt="image" src="https://github.com/user-attachments/assets/145f4ece-af2f-4a45-a3c1-45ae5d3c7e7f" />
|
||||
|
||||
Inspect request and responses:
|
||||
|
||||
<img width="1078" height="668" alt="image" src="https://github.com/user-attachments/assets/947cda4f-9aa1-4fa5-a550-5c469968c1d9" />
|
||||
|
||||
Manually load and unload models:
|
||||
|
||||
<img width="1088" height="659" alt="image" src="https://github.com/user-attachments/assets/b6b850f3-c5b0-4c14-ba90-be2de25b51c7" />
|
||||
|
||||
Real time log streaming:
|
||||
|
||||
<img width="1087" height="668" alt="image" src="https://github.com/user-attachments/assets/9bb0c362-862c-4e68-820c-4c977fc9de4e" />
|
||||
|
||||
## Installation
|
||||
|
||||
llama-swap can be installed in multiple ways
|
||||
|
||||
1. Docker
|
||||
2. Homebrew (macOS and Linux)
|
||||
3. MacPorts (macOS)
|
||||
4. WinGet
|
||||
5. From release binaries
|
||||
6. From source
|
||||
|
||||
### Docker Install ([download images](https://github.com/mostlygeek/llama-swap/pkgs/container/llama-swap))
|
||||
|
||||
Two types of container images are built nightly for llama-swap:
|
||||
|
||||
1. A unified container with llama-server, ik-llama-server, stable-diffusion.cpp, whisper.cpp and llama-swap built from source. This is only available for cuda and vulkan but has more capabilities. This one is recommended for use.
|
||||
2. A legacy image that is based on llama.cpp's images and llama-swap copied into the container. Use this one if you prefer to stay close to llama.cpp's container images.
|
||||
|
||||
#### Unified container (Recommended)
|
||||
|
||||
```shell
|
||||
$ docker pull ghcr.io/mostlygeek/llama-swap:unified-cuda
|
||||
|
||||
# run with a custom configuration and models directory
|
||||
$ docker run -it --rm --runtime nvidia -p 9292:8080 \
|
||||
-v /path/to/models:/models \
|
||||
-v /path/to/custom/config.yaml:/etc/llama-swap/config/config.yaml \
|
||||
ghcr.io/mostlygeek/llama-swap:unified-cuda
|
||||
```
|
||||
|
||||
#### Legacy container
|
||||
|
||||
```shell
|
||||
$ docker pull ghcr.io/mostlygeek/llama-swap:cuda
|
||||
|
||||
# run with a custom configuration and models directory
|
||||
$ docker run -it --rm --runtime nvidia -p 9292:8080 \
|
||||
-v /path/to/models:/models \
|
||||
-v /path/to/custom/config.yaml:/app/config.yaml \
|
||||
ghcr.io/mostlygeek/llama-swap:cuda
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>
|
||||
more examples
|
||||
</summary>
|
||||
|
||||
```shell
|
||||
# pull latest images per platform
|
||||
docker pull ghcr.io/mostlygeek/llama-swap:cpu
|
||||
docker pull ghcr.io/mostlygeek/llama-swap:cuda
|
||||
docker pull ghcr.io/mostlygeek/llama-swap:vulkan
|
||||
docker pull ghcr.io/mostlygeek/llama-swap:intel
|
||||
docker pull ghcr.io/mostlygeek/llama-swap:musa
|
||||
|
||||
# tagged llama-swap, platform and llama-server version images
|
||||
docker pull ghcr.io/mostlygeek/llama-swap:v166-cuda-b6795
|
||||
|
||||
# non-root cuda
|
||||
docker pull ghcr.io/mostlygeek/llama-swap:cuda-non-root
|
||||
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### Homebrew Install (macOS/Linux)
|
||||
|
||||
```shell
|
||||
brew tap mostlygeek/llama-swap
|
||||
brew install llama-swap
|
||||
llama-swap --config path/to/config.yaml --listen localhost:8080
|
||||
```
|
||||
|
||||
### MacPorts (macOS)
|
||||
|
||||
> [!NOTE]
|
||||
> Maintained by MacPorts community - [llama-swap port](https://ports.macports.org/port/llama-swap). It is not an official part of llama-swap.
|
||||
|
||||
```shell
|
||||
sudo port install llama-swap
|
||||
llama-swap --config path/to/config.yaml --listen localhost:8080
|
||||
```
|
||||
|
||||
### WinGet Install (Windows)
|
||||
|
||||
> [!NOTE]
|
||||
> WinGet is maintained by community contributor [Dvd-Znf](https://github.com/Dvd-Znf) ([#327](https://github.com/mostlygeek/llama-swap/issues/327)). It is not an official part of llama-swap.
|
||||
|
||||
```shell
|
||||
# install
|
||||
C:\> winget install llama-swap
|
||||
|
||||
# upgrade
|
||||
C:\> winget upgrade llama-swap
|
||||
```
|
||||
|
||||
### Pre-built Binaries
|
||||
|
||||
Binaries are available on the [release](https://github.com/mostlygeek/llama-swap/releases) page for Linux, Mac, Windows and FreeBSD.
|
||||
|
||||
### Building from source
|
||||
|
||||
1. Building requires Go and Node.js (for UI).
|
||||
1. `git clone https://github.com/mostlygeek/llama-swap.git`
|
||||
1. `make clean all`
|
||||
1. look in the `build/` subdirectory for the llama-swap binary
|
||||
|
||||
## Configuration
|
||||
|
||||
```yaml
|
||||
# minimum viable config.yaml
|
||||
|
||||
models:
|
||||
model1:
|
||||
cmd: llama-server --port ${PORT} --model /path/to/model.gguf
|
||||
```
|
||||
|
||||
That's all you need to get started:
|
||||
|
||||
1. `models` - holds all model configurations
|
||||
2. `model1` - the ID used in API calls
|
||||
3. `cmd` - the command to run to start the server.
|
||||
4. `${PORT}` - an automatically assigned port number
|
||||
|
||||
Almost all configuration settings are optional and can be added one step at a time:
|
||||
|
||||
- Advanced features
|
||||
- `matrix` to run concurrent models with a custom swap logic DSL
|
||||
- `hooks` to run things on startup
|
||||
- `macros` reusable snippets
|
||||
- Model customization
|
||||
- `ttl` to automatically unload models
|
||||
- `aliases` to use familiar model names (e.g., "gpt-4o-mini")
|
||||
- `env` to pass custom environment variables to inference servers
|
||||
- `cmdStop` gracefully stop Docker/Podman containers
|
||||
- `useModelName` to override model names sent to upstream servers
|
||||
- `${PORT}` automatic port variables for dynamic port assignment
|
||||
- `filters` rewrite parts of requests before sending to the upstream server
|
||||
|
||||
See the [configuration documentation](docs/configuration.md) for all options.
|
||||
|
||||
## How does llama-swap work?
|
||||
|
||||
When a request is made to an OpenAI compatible endpoint, llama-swap will extract the `model` value and load the appropriate server configuration to serve it. If the wrong upstream server is running, it will be replaced with the correct one. This is where the "swap" part comes in. The upstream server is automatically swapped to handle the request correctly.
|
||||
|
||||
In the most basic configuration llama-swap handles one model at a time. For more advanced use cases, using a `matrix` allows multiple models to be loaded at the same time. You have complete control over how your system resources are used.
|
||||
|
||||
## Reverse Proxy Configuration (nginx)
|
||||
|
||||
If you deploy llama-swap behind nginx, disable response buffering for streaming endpoints. By default, nginx buffers responses which breaks Server‑Sent Events (SSE) and streaming chat completion. ([#236](https://github.com/mostlygeek/llama-swap/issues/236))
|
||||
|
||||
Recommended nginx configuration snippets:
|
||||
|
||||
```nginx
|
||||
# SSE for UI events/logs
|
||||
location /api/events {
|
||||
proxy_pass http://your-llama-swap-backend;
|
||||
proxy_buffering off;
|
||||
proxy_cache off;
|
||||
}
|
||||
|
||||
# Streaming chat completions (stream=true)
|
||||
location /v1/chat/completions {
|
||||
proxy_pass http://your-llama-swap-backend;
|
||||
proxy_buffering off;
|
||||
proxy_cache off;
|
||||
}
|
||||
```
|
||||
|
||||
As a safeguard, llama-swap also sets `X-Accel-Buffering: no` on SSE responses. However, explicitly disabling `proxy_buffering` at your reverse proxy is still recommended for reliable streaming behavior.
|
||||
|
||||
## Monitoring Logs on the CLI
|
||||
|
||||
```sh
|
||||
# sends up to the last 10KB of logs
|
||||
$ curl http://host/logs
|
||||
|
||||
# streams combined logs
|
||||
curl -Ns http://host/logs/stream
|
||||
|
||||
# stream llama-swap's proxy status logs
|
||||
curl -Ns http://host/logs/stream/proxy
|
||||
|
||||
# stream logs from upstream processes that llama-swap loads
|
||||
curl -Ns http://host/logs/stream/upstream
|
||||
|
||||
# stream logs only from a specific model
|
||||
curl -Ns http://host/logs/stream/{model_id}
|
||||
|
||||
# stream and filter logs with linux pipes
|
||||
curl -Ns http://host/logs/stream | grep 'eval time'
|
||||
|
||||
# appending ?no-history will disable sending buffered history first
|
||||
curl -Ns 'http://host/logs/stream?no-history'
|
||||
```
|
||||
|
||||
## Do I need to use llama.cpp's server (llama-server)?
|
||||
|
||||
Any OpenAI compatible server would work. llama-swap was originally designed for llama-server and it is the best supported.
|
||||
|
||||
For Python based inference servers like vllm or tabbyAPI it is recommended to run them via podman or docker. This provides clean environment isolation as well as responding correctly to `SIGTERM` signals for proper shutdown.
|
||||
|
||||
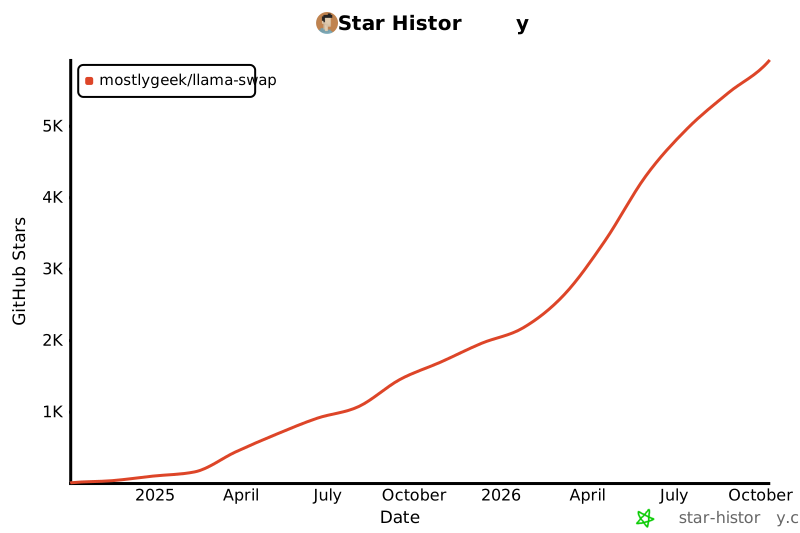
## Star History
|
||||
|
||||
> [!NOTE]
|
||||
> Thank you to everyone who has given this project a ⭐️!
|
||||
|
||||
## Star History
|
||||
|
||||
[](https://www.star-history.com/?repos=mostlygeek%2Fllama-swap&type=date&legend=top-left)
|
||||
@@ -0,0 +1,311 @@
|
||||
# ==============================================================================
|
||||
# llama-swap config — xps9700 (GTX 1650 Ti 3.7GB VRAM, i7-10750H 6c/12t, 15 GiB)
|
||||
#
|
||||
# x570-style single-endpoint stack: llama-swap owns :8080, spawns/kills
|
||||
# llama-server per requested `model` field, idle-unloads after TTL.
|
||||
# All per-model tuning migrated verbatim from envs/.env.* (benchmarks
|
||||
# 2026-05-05/06 + MoE work 2026-07-10 — see docs/FINDINGS.md).
|
||||
#
|
||||
# Edit this file → `docker restart llama_swap_stack` (config is bind-mounted).
|
||||
# ==============================================================================
|
||||
|
||||
healthCheckTimeout: 600 # 35B MoE mmap first-touch can take minutes
|
||||
logLevel: info
|
||||
startPort: 5800
|
||||
|
||||
macros:
|
||||
# t=6 physical cores only — HT hurts (FINDINGS.md §5)
|
||||
"server-base": >
|
||||
/app/llama-server
|
||||
--host 127.0.0.1 --port ${PORT}
|
||||
--threads 6 --threads-batch 6
|
||||
--flash-attn on
|
||||
|
||||
# upstream master build (newer MoE perf work); needs its own libs
|
||||
"server-upstream": >
|
||||
/app-upstream/llama-server
|
||||
--host 127.0.0.1 --port ${PORT}
|
||||
--threads 6 --threads-batch 6
|
||||
--flash-attn on
|
||||
|
||||
# ik_llama.cpp: -ser/-fmoe/-rtr, fast IQ CPU kernels (flag names differ: -fa)
|
||||
# needs env: LD_LIBRARY_PATH=/app-ik (own libllama/libggml, symbol-incompatible with turboquant's)
|
||||
"server-ik": >
|
||||
/app-ik/llama-server
|
||||
--host 127.0.0.1 --port ${PORT}
|
||||
--threads 6 --threads-batch 6 -fa on
|
||||
|
||||
"q8-kv": "--cache-type-k q8_0 --cache-type-v q8_0"
|
||||
"q4-kv": "--cache-type-k q4_0 --cache-type-v q4_0"
|
||||
"turbo2-kv": "--cache-type-k turbo2 --cache-type-v turbo2"
|
||||
|
||||
# MoE offload: dense backbone on GPU, routed experts in RAM/page cache.
|
||||
# mmap (no mlock) mandatory for files > RAM.
|
||||
"moe-offload": "--n-gpu-layers 99 --cpu-moe --jinja"
|
||||
|
||||
groups:
|
||||
# Resident duo for pi: main coding model + fast subagent stay loaded together.
|
||||
# VRAM split (2026-07-10): qwen3-4b gets the WHOLE GPU (ngl 99) — ornith's
|
||||
# experts never touched VRAM anyway and its dense-on-GPU split starved qwen
|
||||
# to 176 MiB / 10 t/s. Ornith runs fully CPU (page-cache resident, 3B active).
|
||||
# Threads: main 6 / sub 3 — contention only during overlap.
|
||||
"duo":
|
||||
swap: false
|
||||
exclusive: true
|
||||
members: ["ornith-35b-duo", "qwen3-4b-duo"]
|
||||
|
||||
models:
|
||||
|
||||
# ── pi resident duo ─────────────────────────────────────────────────────────
|
||||
|
||||
"ornith-35b-duo":
|
||||
name: "Ornith 35B (duo main)"
|
||||
description: "Duo variant: fully CPU (GPU reserved for qwen3-4b-duo). CUDA hidden — even ngl 0 tries a ~1GB pp compute buffer"
|
||||
env:
|
||||
- "CUDA_VISIBLE_DEVICES="
|
||||
cmd: |
|
||||
${server-base} ${q8-kv}
|
||||
--model /models/deepreinforce-ai_Ornith-1.0-35B-Q2_K_L.gguf
|
||||
--n-gpu-layers 0 --jinja
|
||||
--ctx-size 32768
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 1
|
||||
ttl: 0
|
||||
|
||||
"qwen3-4b-duo":
|
||||
name: "Qwen3 4B (duo subagent)"
|
||||
description: "Duo subagent: full GPU (ngl 99), 3 threads, gate-clean JSON"
|
||||
cmd: |
|
||||
/app/llama-server
|
||||
--host 127.0.0.1 --port ${PORT}
|
||||
--threads 3 --threads-batch 3
|
||||
--flash-attn on ${q4-kv}
|
||||
--model /models/Qwen3-4B-Q4_K_M.gguf
|
||||
--n-gpu-layers 99
|
||||
--ctx-size 16384
|
||||
--batch-size 512 --ubatch-size 256
|
||||
--cont-batching --parallel 1
|
||||
ttl: 0
|
||||
|
||||
# ── MoE offload models (2026-07-10) ────────────────────────────────────────
|
||||
|
||||
"gpt-oss-20b":
|
||||
name: "gpt-oss-20b MXFP4"
|
||||
description: "20.9B/3.6B-active MoE, native MXFP4. 16.7 tg / 29.5 pp (n-cpu-moe 21: last 3 expert layers in VRAM, +16%)"
|
||||
cmd: |
|
||||
${server-base} ${q8-kv}
|
||||
--model /models/gpt-oss-20b-mxfp4.gguf
|
||||
--n-gpu-layers 99 --n-cpu-moe 21 --jinja
|
||||
--ctx-size 32768
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 1
|
||||
ttl: 300
|
||||
|
||||
"qwen36-35b":
|
||||
name: "Qwen3.6-35B-A3B UD-IQ4_XS"
|
||||
description: "35B/3B-active MoE, 17.7GB mmap > RAM. Stop heavy containers first"
|
||||
cmd: |
|
||||
${server-base} ${moe-offload} ${q8-kv}
|
||||
--model /models/Qwen3.6-35B-A3B-UD-IQ4_XS.gguf
|
||||
--ctx-size 32768
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 1
|
||||
ttl: 300
|
||||
|
||||
"qwen36-35b-q2":
|
||||
name: "Qwen3.6-35B-A3B UD-Q2_K_XL"
|
||||
description: "DAILY DRIVER 35B: 23.0 tg / 36 pp. ds4 asymmetric recipe (dense high-bit, experts 2-bit), 12.3GB page-cache resident, last 3 expert layers in VRAM. Gates pass"
|
||||
cmd: |
|
||||
${server-base} ${q8-kv}
|
||||
--model /models/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf
|
||||
--n-gpu-layers 99 --n-cpu-moe 37 --jinja
|
||||
--ctx-size 32768
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 1
|
||||
ttl: 300
|
||||
|
||||
"ornith-35b":
|
||||
name: "Ornith-1.0-35B Q2_K_L"
|
||||
description: "SPEED KING: 29.1 tg / 66 pp. RL coding finetune (Qwen3.5-MoE arch), 13.1GB page-cache resident, 3 expert layers in VRAM, thinking model. MIT. Gates pass"
|
||||
cmd: |
|
||||
${server-base} ${q8-kv}
|
||||
--model /models/deepreinforce-ai_Ornith-1.0-35B-Q2_K_L.gguf
|
||||
--n-gpu-layers 99 --n-cpu-moe 37 --jinja
|
||||
--ctx-size 32768
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 1
|
||||
ttl: 300
|
||||
|
||||
"ornith-35b-iq4":
|
||||
name: "Ornith-1.0-35B IQ4_XS"
|
||||
description: "Quality-first variant, 18.8GB mmap > RAM = ~2.8 t/s thrash. Batch jobs only (or post-RAM-upgrade)"
|
||||
cmd: |
|
||||
${server-base} ${moe-offload} ${q8-kv}
|
||||
--model /models/deepreinforce-ai_Ornith-1.0-35B-IQ4_XS.gguf
|
||||
--ctx-size 32768
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 1
|
||||
ttl: 300
|
||||
|
||||
# ── ik_llama.cpp experimental variants ──────────────────────────────────────
|
||||
|
||||
"qwen36-35b-q2-ik":
|
||||
name: "Qwen3.6-35B Q2_K_XL (ik_llama)"
|
||||
description: "ik build: 18.0 tg / 42 pp — loses decode to main build (23.0), wins prefill. -ser 6,1 active. Experimental only"
|
||||
env:
|
||||
- "LD_LIBRARY_PATH=/app-ik"
|
||||
cmd: |
|
||||
${server-ik} ${q8-kv}
|
||||
--model /models/Qwen3.6-35B-A3B-UD-Q2_K_XL.gguf
|
||||
--n-gpu-layers 99 --n-cpu-moe 37 --jinja -ser 6,1
|
||||
--ctx-size 16384
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--parallel 1
|
||||
ttl: 300
|
||||
|
||||
"gpt-oss-20b-upstream":
|
||||
name: "gpt-oss-20b (upstream master)"
|
||||
description: "Upstream Jul-2026 build comparison"
|
||||
env:
|
||||
- "LD_LIBRARY_PATH=/app-upstream"
|
||||
cmd: |
|
||||
${server-upstream} ${q8-kv}
|
||||
--model /models/gpt-oss-20b-mxfp4.gguf
|
||||
--n-gpu-layers 99 --n-cpu-moe 21 --jinja
|
||||
--ctx-size 32768
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 1
|
||||
ttl: 300
|
||||
|
||||
# ── Dense 9B (RAM-bandwidth-bound, ~4.4 t/s) ───────────────────────────────
|
||||
|
||||
"ornith-9b":
|
||||
name: "Ornith-1.0-9B Q8_0"
|
||||
description: "Coding 9B, MIT. ~4.4 t/s, mlock-pinned"
|
||||
cmd: |
|
||||
${server-base} ${turbo2-kv}
|
||||
--model /models/ornith-9b-Q8_0.gguf
|
||||
--n-gpu-layers 11
|
||||
--ctx-size 32768
|
||||
--batch-size 512 --ubatch-size 256
|
||||
--cont-batching --parallel 1
|
||||
--no-mmap --mlock --jinja
|
||||
ttl: 300
|
||||
|
||||
"qwen35-9b":
|
||||
name: "Qwen3.5-9B Q8_0"
|
||||
description: "Reasoning distill. 4.38 t/s measured, mlock-pinned"
|
||||
cmd: |
|
||||
${server-base} ${turbo2-kv}
|
||||
--model /models/Qwen3.5-9B.Q8_0.gguf
|
||||
--n-gpu-layers 11
|
||||
--ctx-size 32768
|
||||
--batch-size 512 --ubatch-size 256
|
||||
--cont-batching --parallel 1
|
||||
--no-mmap --mlock
|
||||
ttl: 300
|
||||
|
||||
# ── Pure-GPU small models ───────────────────────────────────────────────────
|
||||
|
||||
"qwen3-4b":
|
||||
name: "Qwen3-4B Q4_K_M"
|
||||
description: "44 t/s @ 16K. NEVER turbo KV (PPL 438 @ 32K — FINDINGS.md §2)"
|
||||
cmd: |
|
||||
${server-base} ${q4-kv}
|
||||
--model /models/Qwen3-4B-Q4_K_M.gguf
|
||||
--n-gpu-layers 99
|
||||
--ctx-size 16384
|
||||
--batch-size 512 --ubatch-size 256
|
||||
--cont-batching --parallel 1
|
||||
ttl: 300
|
||||
|
||||
"smollm3-3b":
|
||||
name: "SmolLM3-3B Q4_K_M"
|
||||
description: "58 t/s @ 32K, thinking+tools, 2 slots"
|
||||
cmd: |
|
||||
${server-base} ${turbo2-kv}
|
||||
--model /models/HuggingFaceTB_SmolLM3-3B-Q4_K_M.gguf
|
||||
--n-gpu-layers 99
|
||||
--ctx-size 32768
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 2
|
||||
ttl: 300
|
||||
|
||||
"gemma4-e2b":
|
||||
name: "Gemma 4 E2B Q4_K_M"
|
||||
description: "66 t/s, multimodal, 131K ctx (MQA tiny KV; f16 KV — turbo2 worse)"
|
||||
cmd: |
|
||||
${server-base}
|
||||
--cache-type-k f16 --cache-type-v f16
|
||||
--model /models/google_gemma-4-E2B-it-Q4_K_M.gguf
|
||||
--n-gpu-layers 99
|
||||
--ctx-size 131072
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 2
|
||||
ttl: 300
|
||||
|
||||
"gemma4-e4b":
|
||||
name: "Gemma 4 E4B Q4_K_M"
|
||||
description: "32 t/s @ 24K, multimodal. ngl=42 needs free VRAM"
|
||||
cmd: |
|
||||
${server-base} ${turbo2-kv}
|
||||
--model /models/google_gemma-4-E4B-it-Q4_K_M.gguf
|
||||
--n-gpu-layers 42
|
||||
--ctx-size 24576
|
||||
--batch-size 1024 --ubatch-size 512
|
||||
--cont-batching --parallel 1
|
||||
ttl: 300
|
||||
|
||||
# ── bigctx variants (-nkvo: KV in RAM over PCIe, ~8 GB/s) ──────────────────
|
||||
|
||||
"smollm3-3b-bigctx":
|
||||
name: "SmolLM3-3B bigctx 65K"
|
||||
description: "~15 t/s @ 50% fill, KV in RAM"
|
||||
cmd: |
|
||||
${server-base} ${turbo2-kv}
|
||||
--model /models/HuggingFaceTB_SmolLM3-3B-Q4_K_M.gguf
|
||||
--n-gpu-layers 99
|
||||
--ctx-size 65536
|
||||
--batch-size 512 --ubatch-size 256
|
||||
--cont-batching --parallel 1
|
||||
--no-kv-offload
|
||||
ttl: 300
|
||||
|
||||
"gemma4-e2b-bigctx":
|
||||
name: "Gemma 4 E2B bigctx 393K"
|
||||
description: "~17 t/s @ 50% fill. q4_0 KV (turbo2 worse on MQA)"
|
||||
cmd: |
|
||||
${server-base} ${q4-kv}
|
||||
--model /models/google_gemma-4-E2B-it-Q4_K_M.gguf
|
||||
--n-gpu-layers 99
|
||||
--ctx-size 393216
|
||||
--batch-size 512 --ubatch-size 256
|
||||
--cont-batching --parallel 1
|
||||
--no-kv-offload
|
||||
ttl: 300
|
||||
|
||||
"gemma4-e4b-bigctx":
|
||||
name: "Gemma 4 E4B bigctx 163K"
|
||||
description: "~18 t/s @ 50% fill, KV in RAM"
|
||||
cmd: |
|
||||
${server-base} ${turbo2-kv}
|
||||
--model /models/google_gemma-4-E4B-it-Q4_K_M.gguf
|
||||
--n-gpu-layers 42
|
||||
--ctx-size 163840
|
||||
--batch-size 512 --ubatch-size 128
|
||||
--cont-batching --parallel 1
|
||||
--no-kv-offload
|
||||
ttl: 300
|
||||
|
||||
"qwen3-4b-bigctx":
|
||||
name: "Qwen3-4B bigctx 24K"
|
||||
description: "~11 t/s @ 50% fill. q4_0 KV only (turbo broken)"
|
||||
cmd: |
|
||||
${server-base} ${q4-kv}
|
||||
--model /models/Qwen3-4B-Q4_K_M.gguf
|
||||
--n-gpu-layers 20
|
||||
--ctx-size 24576
|
||||
--batch-size 512 --ubatch-size 256
|
||||
--cont-batching --parallel 1
|
||||
--no-kv-offload
|
||||
ttl: 300
|
||||
Executable
BIN
Binary file not shown.
Binary file not shown.
Reference in New Issue
Block a user